LLM Leaderboard?
Build Your Own.
Generic leaderboards rank models on standardized tests. But your production task isn't standardized. Create a personal AI model leaderboard that ranks 100+ models on YOUR actual use case.
The Problem with LLM Leaderboards
LMSYS Chatbot Arena, Open LLM Leaderboard, MMLU rankings — they all suffer from the same problems:
Benchmark Contamination
Models may have trained on test data. A model scoring 92% on MMLU might score 65% on a novel, unseen task — like YOUR use case.
No Cost Data
Leaderboards rank by accuracy alone. A model that's 3% better but costs 50x more isn't the "best" for production workloads.
Generic Tasks
MMLU tests general knowledge. HumanEval tests Python. Your customer support, legal review, or data extraction pipeline isn't tested anywhere.
Subjective Voting
Arena-style leaderboards use human voting — subjective, noisy, and biased toward verbose/confident-sounding responses.
Our Own Live Leaderboard: October 2026
To practice what we preach, here is OpenMark's own leaderboard: three hard tasks, re-run every month on current flagship and budget models, with the exact task definitions one click away so you can reproduce every number.
Notice how many models tie at 100%. We publish that honestly, because it is the whole point: on a well-specified task, most current frontier models are simply good. What actually separates them is price and speed (below, some models match the top score while costing up to 102x less per run), and how they behave on your task, with your data and your edge cases. That last part is exactly what no public leaderboard, including this one, can tell you.
Logical Reasoning: Deduction Gauntlet
Knights-and-liars, constraint placement, combinatorics, parity reasoning, and syllogistic validity. Unique answers, strict formats. (6 tests, 3 passes per model, strict deterministic scoring.)
| # | Model | Score | Cost/run |
|---|---|---|---|
| 1 | GPT-5.6 Luna | 100.0% | $0.0020 |
| 2 | DeepSeek-V4.1-Flash | 100.0% | $0.0050 |
| 3 | Grok 4.5 | 100.0% | $0.031 |
| 4 | DeepSeek-V4-Pro | 100.0% | $0.035 |
| 5 | GPT-5.6 Sol @high | 100.0% | $0.037 |
| 6 | GPT-5.6 Sol | 100.0% | $0.037 |
| 7 | GLM-5.2 | 100.0% | $0.049 |
| 8 | Claude Opus 5 | 100.0% | $0.079 |
| 9 | Claude Opus 5 @high | 100.0% | $0.080 |
| 10 | Gemini 3.1 Pro | 100.0% | $0.118 |
| 11 | Gemini 3.1 Pro @high | 100.0% | $0.146 |
| 12 | Grok 4.1 Fast | 72.2% | $0.0026 |
| 13 | Gemini 3.1 Flash-Lite | 66.7% | $0.0025 |
| 14 | Mistral Medium 3.5 | 66.7% | $0.056 |
| 15 | MiniMax-M3 | 50.0% | $0.0082 |
| 16 | Claude Haiku 4.5 | 44.4% | $0.018 |
Run this exact logical reasoning benchmark yourself (free to load)
SQL Generation: Production Queries
PostgreSQL queries that separate juniors from seniors - NULL-safe anti-joins, ranking with ties, recursive CTEs, and window frames. (10 tests, 3 passes per model, strict deterministic scoring.)
| # | Model | Score | Cost/run |
|---|---|---|---|
| 1 | Gemini 3.1 Flash-Lite | 100.0% | $0.0014 |
| 2 | Grok 4.1 Fast | 100.0% | $0.0030 |
| 3 | GPT-5.6 Luna | 100.0% | $0.0030 |
| 4 | Claude Haiku 4.5 | 100.0% | $0.0058 |
| 5 | DeepSeek-V4.1-Flash | 100.0% | $0.013 |
| 6 | GPT-5.6 Sol | 100.0% | $0.052 |
| 7 | GPT-5.6 Sol @high | 100.0% | $0.060 |
| 8 | Gemini 3.1 Pro @high | 100.0% | $0.130 |
| 9 | Gemini 3.1 Pro | 100.0% | $0.134 |
| 10 | Grok 4.5 | 98.9% | $0.029 |
| 11 | DeepSeek-V4-Pro | 98.9% | $0.149 |
| 12 | GLM-5.2 | 97.8% | $0.059 |
| 13 | Mistral Medium 3.5 | 97.5% | $0.0077 |
| 14 | Claude Opus 5 @high | 96.1% | $0.061 |
| 15 | Claude Opus 5 | 94.1% | $0.063 |
| 16 | MiniMax-M3 | 87.2% | $0.0080 |
Run this exact SQL generation benchmark yourself (free to load)
Translation: Professional Constraints
Business translation under real-world constraints - fixed glossaries, locale number and date formats, formal register, and adversarial source text. (8 tests, 3 passes per model, strict deterministic scoring.)
| # | Model | Score | Cost/run |
|---|---|---|---|
| 1 | GPT-5.6 Luna | 100.0% | $0.0010 |
| 2 | Claude Haiku 4.5 | 100.0% | $0.0024 |
| 3 | Grok 4.1 Fast | 100.0% | $0.0026 |
| 4 | Mistral Medium 3.5 | 100.0% | $0.0031 |
| 5 | GPT-5.6 Sol | 100.0% | $0.011 |
| 6 | GPT-5.6 Sol @high | 100.0% | $0.014 |
| 7 | DeepSeek-V4-Pro | 100.0% | $0.015 |
| 8 | Grok 4.5 | 100.0% | $0.020 |
| 9 | Claude Opus 5 | 100.0% | $0.033 |
| 10 | Gemini 3.1 Pro | 100.0% | $0.094 |
| 11 | Gemini 3.1 Pro @high | 100.0% | $0.101 |
| 12 | Gemini 3.1 Flash-Lite | 97.9% | $0.0005 |
| 13 | DeepSeek-V4.1-Flash | 97.9% | $0.0056 |
| 14 | GLM-5.2 | 96.9% | $0.039 |
| 15 | Claude Opus 5 @high | 87.5% | $0.030 |
| 16 | MiniMax-M3 | 86.8% | $0.0045 |
Run this exact translation benchmark yourself (free to load)
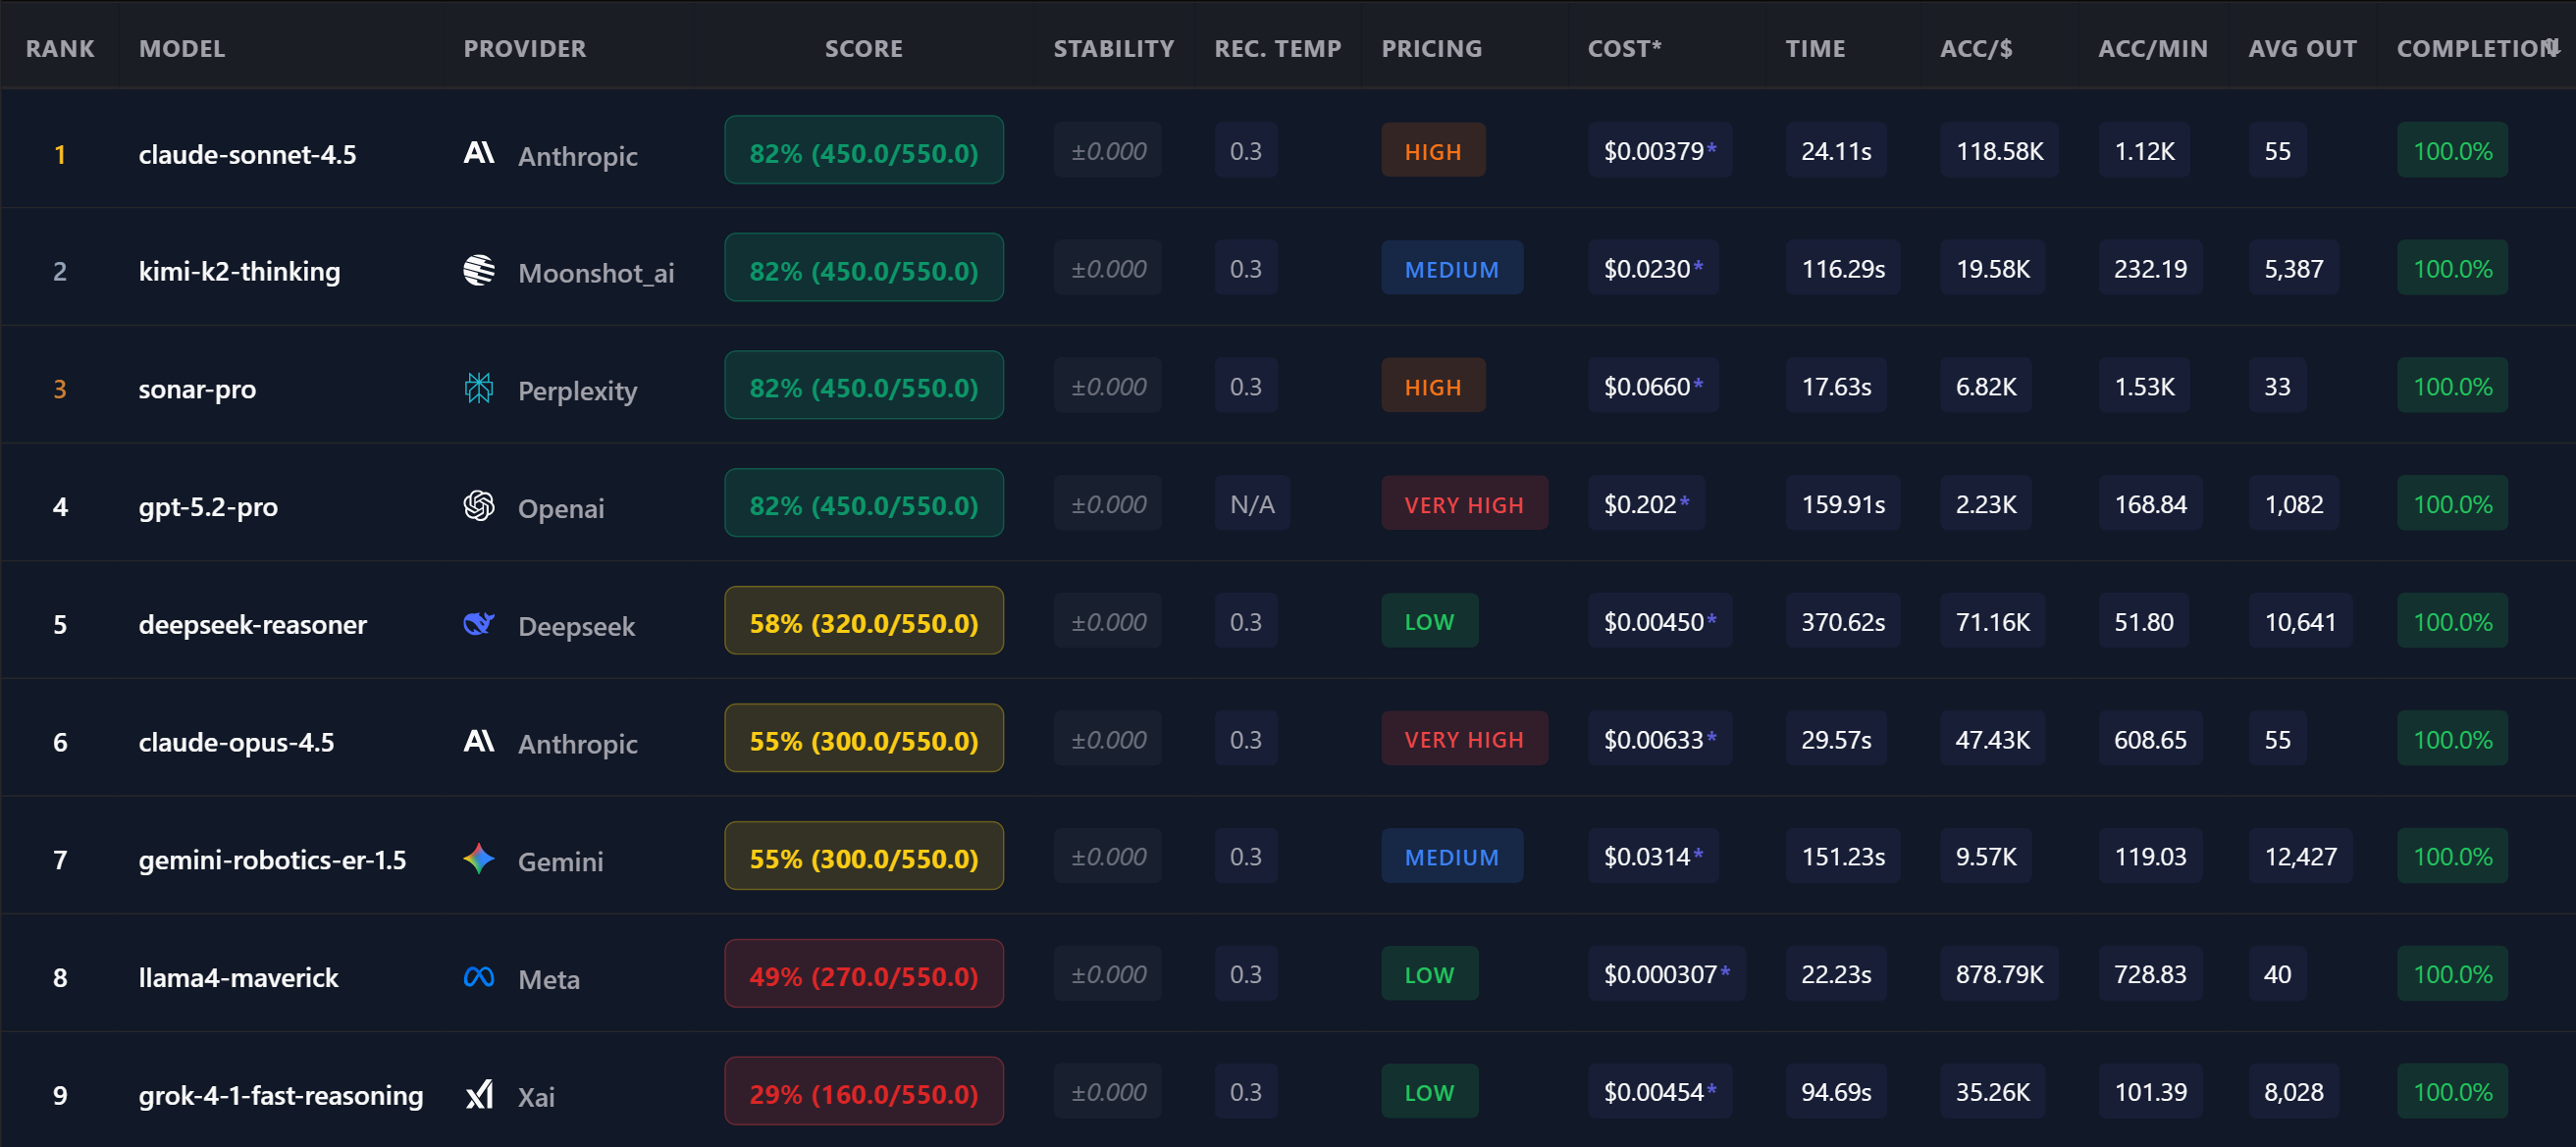
A real OpenMark leaderboard — YOUR task, YOUR rankings, YOUR data.
Your Custom LLM Leaderboard
OpenMark lets you create a leaderboard that matters — one based on YOUR actual prompts and use cases:
Leaderboard You Can Sort
Unlike static leaderboards, OpenMark's results table is interactive. Sort by any column to find the model that fits your priority:
| Rank | Model | Score | Cost | Acc/$ | Speed |
|---|---|---|---|---|---|
| 1 | claude-sonnet-4.5 Anthropic | 82% | $0.0038 | 118.5K | 24s |
| 2 | gpt-4o OpenAI | 78% | $0.0045 | 95.2K | 18s |
| 3 | deepseek-v3 DeepSeek | 75% | $0.0003 | 878.8K | 22s |
| 4 | gemini-2.5-flash | 73% | $0.0005 | 450.1K | 15s |
↑ Example data. YOUR leaderboard will reflect YOUR task's results.
"We replaced our weekly leaderboard check with a monthly OpenMark benchmark on our actual production prompts. We caught a model regression that leaderboards missed — our production pipeline would have broken."
FAQ
How is this different from the Chatbot Arena leaderboard?
Chatbot Arena ranks by human voting on random conversations — subjective and generic. OpenMark ranks by deterministic scoring on YOUR actual prompts, with cost and speed data included.
Can I compare my rankings over time?
Yes. Run the same benchmark monthly to track model improvements, regressions, and pricing changes. Your benchmark history is saved for comparison.
Does this replace standard benchmarks?
Not entirely. Standard benchmarks are useful for general capability assessment. But for production decisions, you need a leaderboard based on YOUR specific task. Learn more about custom benchmarking →
Can you run the benchmark for me?
Yes. The audit service ($299–$499) covers one recurring task across 10–20 models in 48 hours. Optional retainer at $500–$1,000/month for ongoing re-runs as new models ship. Best-fit for tasks with measurable outputs (classification, extraction, RAG grading, routing, moderation). Details on the audit page →
Why Teams Use OpenMark AI
No provider accounts required. OpenMark AI handles every API call via credits — just describe your task and run.
No Python SDK, no CLI, no notebook. Works for PMs, founders, and teams that don't want to spin up an eval pipeline.
Guided task builder, select models, run, results. No environment setup, no SDK, no configuration files.
Compare models from every major provider in a single benchmark run. Not 4, not "the big 3" — over 100.
Don't want to design the test yourself? Have us run it for you.
If you're researching which model to ship and want a definitive answer for your task instead of more reading — we run the eval for you. Send us your task, we benchmark it across all relevant models (up to 30+) and send back a synthesized report with the recommended primary, fallbacks, cost-at-volume, and re-test triggers. From $299, 48-hour turnaround, no call required.
Build Your Own LLM Leaderboard
Rank 100+ models on YOUR task. Real data, not generic scores.
Free tier — no credit card required.